Building Production-Ready AI Systems
Requires More Than An LLM.
Anyone can write a prompt. Deploying dependable AI in production requires a multi-stage architecture with deterministic domain logic, structured context, schema validation, and strict cost controls.
Why 85% of AI Prototypes Break in Production
Building an LLM demo is easy. Deploying enterprise software that processes high volumes without hallucinations, data leakage, or runaway billing requires deep systems architecture.
Mathematical Drift
Asking probabilistic LLMs to calculate numbers or enforce business rules directly leads to hallucinated arithmetic and compliance violations.
Runaway Token Costs
Without intelligent semantic caching, prompt deduplication, and model routing, user queries burn tokens exponentially and blow budgets.
Security & Data Leakage
Sending raw customer inputs straight to model providers exposes sensitive PII and leaves systems vulnerable to prompt injection attacks.
Untyped Output Crashes
Unenforced markdown responses and hallucinated JSON keys break frontend user sessions and corrupt backend SQL database tables.
Four Core AI Solutions We Build
Engineered for real operational problems, compliance standards, and commercial ROI.
1. AI Product Engineering
We transform AI concepts into complete, market-ready commercial applications. We build user onboarding, multi-tenant state management, access controls, model gateways, and scalable cloud hosting.
2. AI Integration & Modernization
You don't need to rebuild your software from scratch. We embed intelligence directly into your existing web platforms, internal ERPs, and operational tools via clean, typed REST and gRPC API layers.
3. Intelligent Automation & Agentic Workflows
Autonomous multi-step agents that retrieve documents, synthesize business data, and execute tasks across CRM, ERP, and payment pipelines under strictly controlled permissions and human checkpoints.
4. Domain-Specific & Regulated AI
Generic LLMs stumble when applications require strict mathematical rules, domain formulas, or regulatory compliance. We combine AI with pure-code deterministic engines and private RAG vector memory.
The 5-Stage Resilient AI System Pipeline
Click or hover over each layer in our architectural topology below to inspect its production contracts, security boundaries, and engineering guarantees.
Data & Inputs
Domain Logic
Structured Context
AI Orchestration
Application Validation
Data & Inputs
Sanitizes, validates, and authenticates all incoming user and machine data before passing it into the application pipeline.
How We Separate Business Logic From AI Generation
We don't ask the LLM to guess facts or calculate numbers. We enforce rigid Pydantic DTO prompt contracts in Python before the model is ever called.
# 1. Deterministic Domain Engine executes in pure Python (Zero AI Guesswork)
class PlanetaryTransitDTO(BaseModel):
    planet_name: Literal["Jupiter", "Saturn", "Rahu", "Ketu"]
    longitude_degrees: float = Field(..., ge=0.0, lt=360.0)
    current_house: int = Field(..., ge=1, le=12)
    is_retrograde: bool
    ashtakavarga_score: int = Field(..., ge=0, le=8)

# 2. Assembled Context Contract with strict validation
class ContextAssemblyPayload(BaseModel):
    user_id: UUID4
    verified_coordinates: List[PlanetaryTransitDTO]
    active_dasha_lord: str
    allow_speculation: bool = False  # Hard boundary constraint

# 3. Model invocation strictly constrained by schema & semantic cache
async def synthesize_verified_guidance(payload: ContextAssemblyPayload) -> StructuredGuidanceResponse:
    cache_key = hashlib.sha256(payload.model_dump_json().encode()).hexdigest()
    if cached := await redis_cache.get(cache_key):
        return StructuredGuidanceResponse.model_validate_json(cached) # Sub-100ms return, $0 LLM cost

    # Dispatched via Anthropic Claude 3.5 Sonnet / Structured Outputs
    response = await ai_gateway.generate_structured(
        schema=StructuredGuidanceResponse,
        context=payload
    )
    await redis_cache.set(cache_key, response.model_dump_json(), ex=86400)
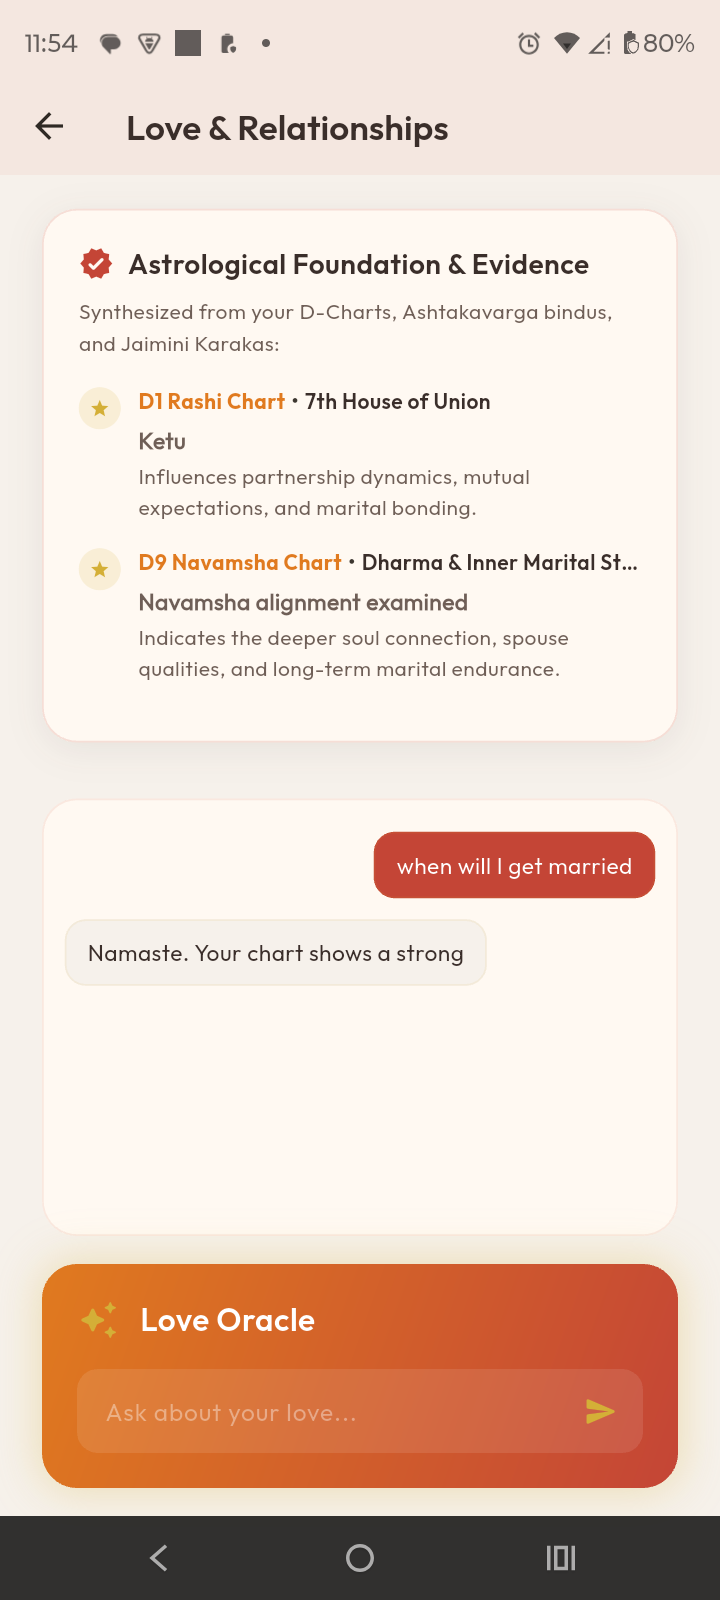
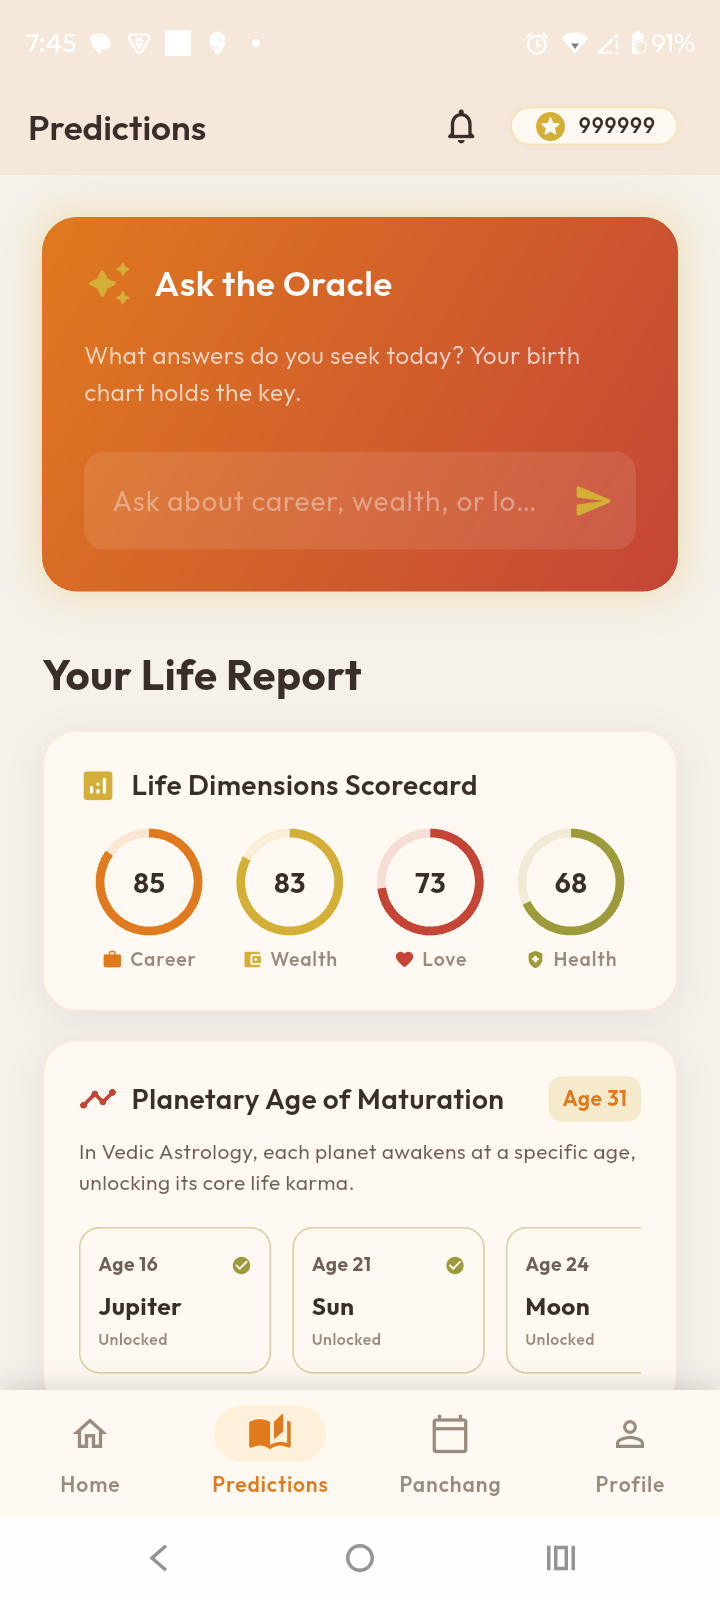
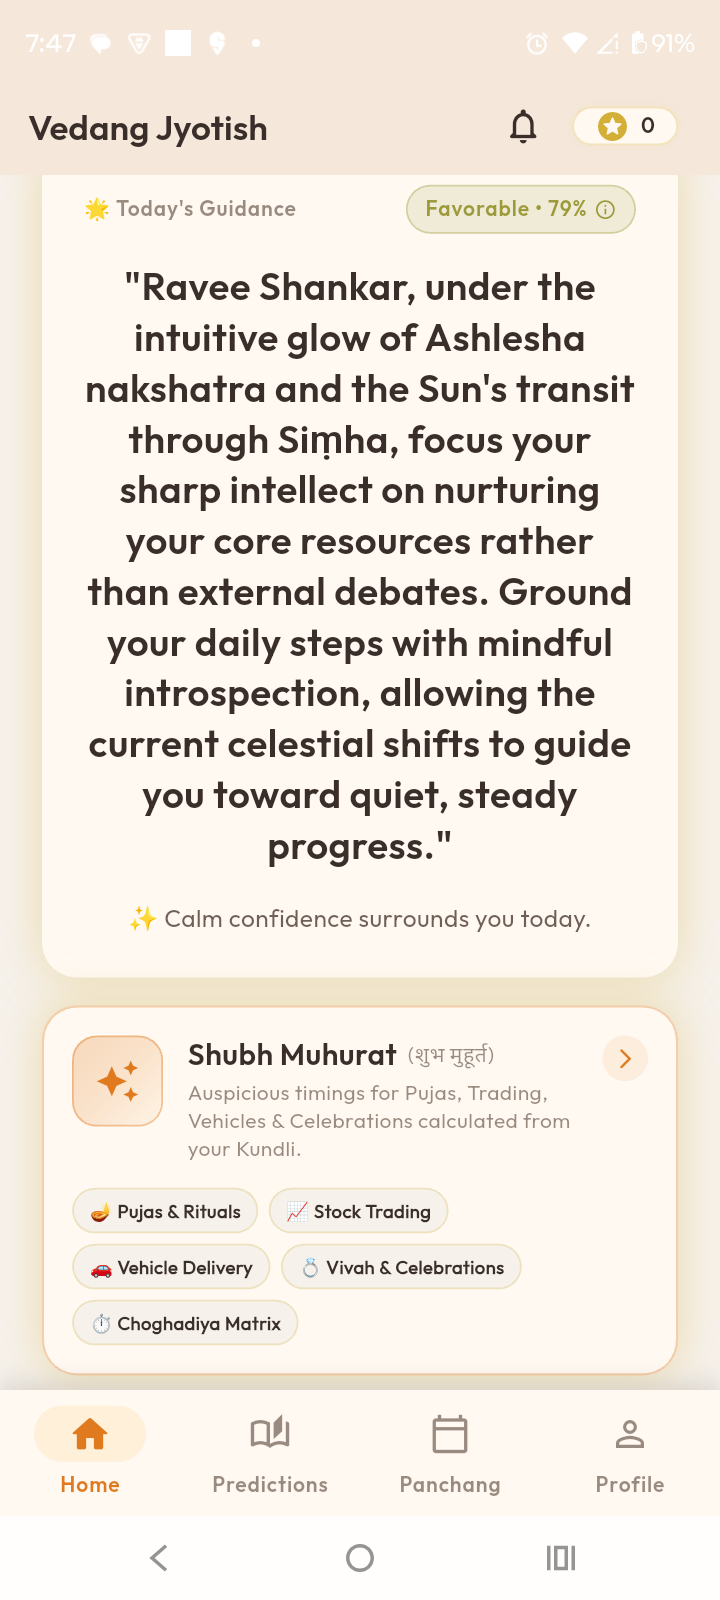
return responseBharatAstro: In-House AI Masterpiece
Live production proof: pairing pure deterministic calculation engines with structured AI synthesis to prevent AI guesswork in complex domain workflows.
Our Production AI Technology Stack
We engineer resilient pipelines using modern languages, reliable vector databases, and enterprise cloud infrastructure.
Languages & Backend
AI Models & Gateways
Vector & Data Stores
Cloud & DevOps
Enterprise Safeguards for AI Deployments
Clear commercial terms and strict data isolation so you can innovate with confidence.
100% IP & Weights Ownership
You own all orchestration code, prompt templates, fine-tuned weights, and system architecture from day one. Zero recurring vendor royalties.
Zero Model Training on Data
We deploy using strict enterprise zero-data-retention API contracts and private endpoints. Your business data is never used to train foundation models.
Private VPC Deployments
Complete deployment inside your dedicated AWS, Google Cloud, or Azure VPC, maintaining compliance with SOC2, HIPAA, and GDPR standards.
Hard Budget & Token Caps
We implement multi-tiered token limits, cost alerting thresholds, and semantic caching so you never receive an unexpected billing surprise.
Frequently Asked Technical Questions
Straightforward engineering answers on model latency, hallucinations, data privacy, and architecture.
How do you protect mission-critical applications from AI hallucinations?
We minimize hallucination risk by strictly separating calculations from generation: mathematical computations, pricing algorithms, and business logic run entirely in fixed code before any AI model is invoked. The AI never calculates numbers; it receives pre-verified facts through typed Pydantic contracts and is restricted to plain-language explanation, followed by automated schema validation on every output.
Is our proprietary data used to train or fine-tune public models?
No. We exclusively use enterprise API agreements (Anthropic Commercial, OpenAI Enterprise, Azure OpenAI, or Google Cloud Vertex AI) that explicitly guarantee zero data retention and legally prohibit using your inputs or outputs for foundation model training. For high-security environments, we also deploy self-hosted open-weights models (such as Llama 3) inside your isolated VPC.
How do you prevent unexpected token cost spikes at high traffic volume?
We implement a 3-layer cost governance system: First, SHA-256 semantic Redis caching serves repeated or similar queries instantly without calling the model, typically cutting API costs by 80%+. Second, our LiteLLM gateway automatically routes simpler tasks to fast, lightweight models (e.g. Claude 3.5 Haiku or GPT-4o-mini). Third, hard per-tenant rate limits and daily quota circuit-breakers prevent budget overruns.
Can you integrate AI systems with our existing SQL databases and internal ERPs?
Yes. As a 14-year full-stack software engineering firm, backend integration is our core strength. We build secure REST, GraphQL, or webhook middleware that safely connects your PostgreSQL, MySQL, SAP, Salesforce, or custom internal systems to the AI orchestration layer with strict schema typing and zero cross-tenant contamination.
What does an initial engagement look like?
We start with a confidential 30-minute Architecture & Data Flow Discovery Call under mutual NDA. We evaluate your current systems, data structures, accuracy requirements, and cost targets. From there, we deliver an architectural blueprint and fixed-bid milestone proposal or agile sprint team plan.
Ready to Architect a Production-Ready AI System?
Schedule a 30-minute technical discovery session with our senior AI systems architects to review your use case, data flows, and infrastructure requirements.